Table of Contents
Problem statement: why scaling microgrids fails on the balance sheet
Developers often deliver technical pilots that fail to scale because finance and operations weren’t aligned from day one. An island microgrid prototype can demonstrate technology, but growth stalls when revenue certainty, interconnection schedules, and operations doctrine diverge—this directly challenges outage resilience objectives. The Puerto Rico outages after Hurricane Maria remain a clear benchmark: stakeholders realized resilience requires repeatable commercial structures, not ad-hoc engineering wins.
Root causes that block scale
– Mismatched capital profiles: lenders demand predictable cash flows; pilot CAPEX often expects public grants. – Interconnection and market risk: extended queue times and ambiguous capacity accreditation erode modeled returns. – Operational fragmentation: vendor-specific controls and no standardized O&M agreement raise lifecycle OPEX. – Product design mismatch: systems built for one site lack modularity, increasing replication cost. Addressing these gaps is a financial exercise as much as a technical one—each unresolved item destroys projected IRR or increases cost of capital.
Financial constructs that enable repeatable scaling
Use structures that convert technical performance into bankable cash flows: – Long-term capacity contracts or hybrid PPAs that pay for resilience attributes as a defined commodity. – Tranching capital: senior debt for core generation/storage, mezzanine for expansion, and grant or tax-equity to improve yield. – Standardized performance guarantees with measurable KPIs—availability, islanding time, and round-trip efficiency—so insurers and rating agencies can underwrite consistently. These tools reduce revenue volatility and make projects comparable across portfolios.
Technical and contractual design principles
– Modular build: repeatable 1–5 MW blocks reduce engineering variation. – Control-layer standardization: open protocols and a single SCADA strategy cut integration time. – Clear commissioning and acceptance milestones tied to payments. – Explicit N-1 and redundancy clauses in O&M contracts so outage scenarios have defined remediation costs. Follow these practices to keep unit costs predictable as you replicate sites.

Operational playbook for maintaining resilience at scale
Operational scaling is where costs compound if ignored. Prioritize: – Centralized operations with regionally distributed field teams. – Remote diagnostics, firmware governance, and fleet-level analytics to push software fixes across assets. – A spare-parts pool sized to worst-case lead times. Common mistakes: treating each site as independent, under-investing in remote monitoring, and deferring preventive maintenance to cut short-term expenses; those choices raise unplanned outage risk and damage investor returns.
Comparative alternatives and when to choose microgrids
Options to consider: full utility upgrade, community solar plus storage, or distributed microgrids. Use financial filters: capital intensity per MW of resilience, time-to-service, and measurable revenue streams for resilience. Choose microgrids when the client values defined outage performance, needs rapid deployment, and can contract resilience as a paid service. Otherwise, grid upgrades may be cheaper for pure energy delivery without resilience premiums.
Key metrics and due diligence checklist
Track metrics that investors will require: levelized cost of resilience, project IRR under outage scenarios, availability percentage, mean time to repair (MTTR), and dispatchable storage depth. Due diligence must include interconnection status, historical outage profiles for the service area, O&M contractual alignment to warranty periods, and supply-chain lead times for critical components.
Final synthesis: aligning finance, operations, and resilience for scale
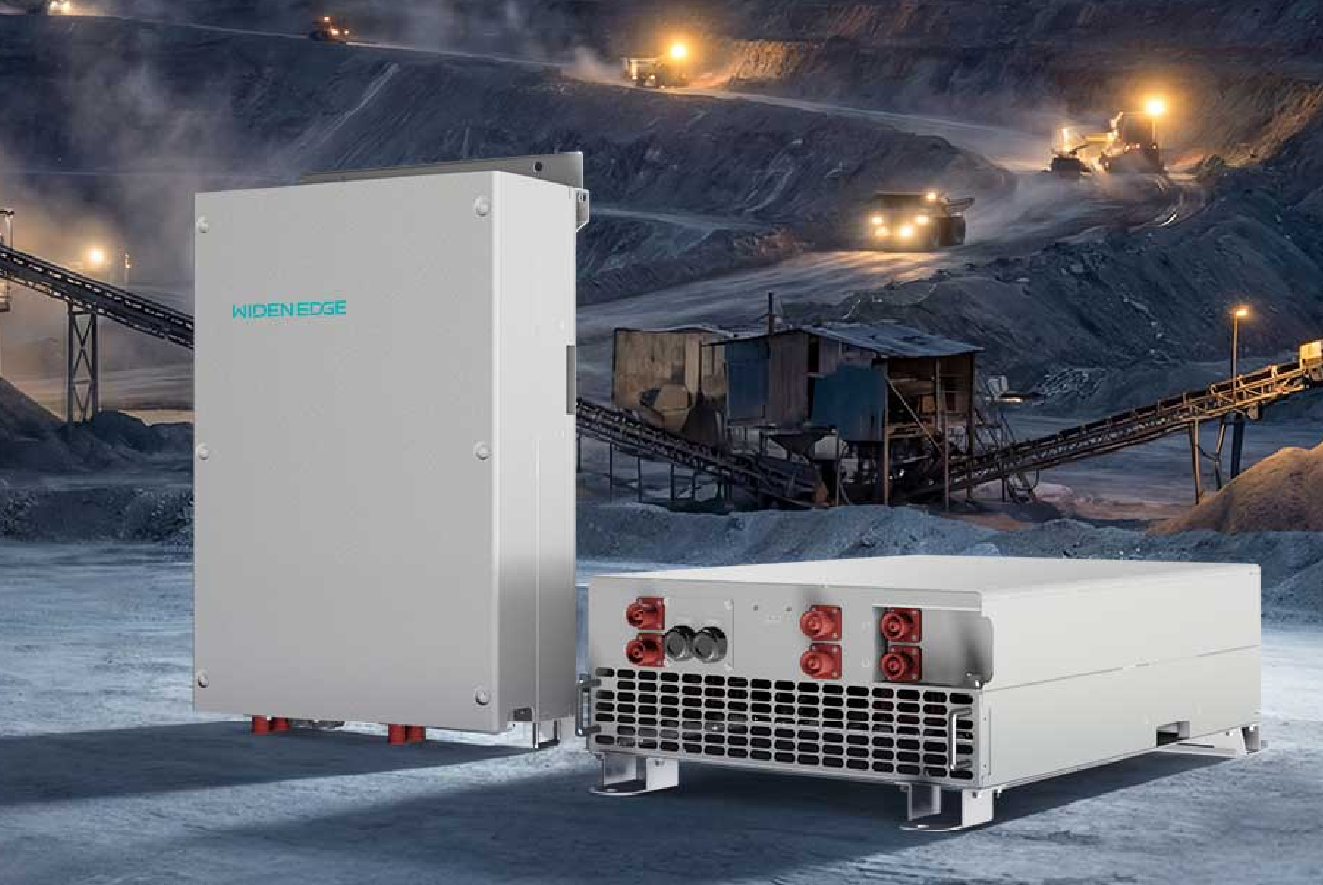
Scaling microgrids is a problem of translation: turn engineering capability into standardized, contractable products that produce predictable cash flows and demonstrable outage outcomes. That translation demands modular designs, bankable performance metrics, and financing that matches operational life. Practical experience shows that projects succeed when teams treat resilience as a priced service and design replication into the contract and tech stack; for pragmatic implementation guidance, consider how WidenEdge integrates performance standards, operational workflows, and financing templates so resilience converts into repeatable, investable projects.