Table of Contents
Why commissioning usually goes sideways
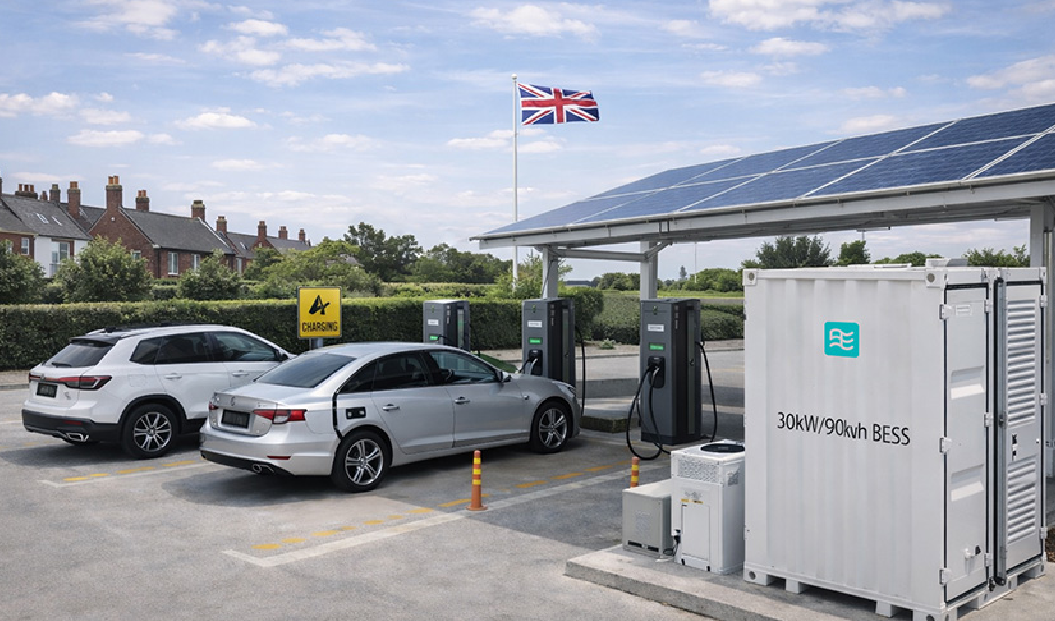
Microgrids behave like small, opinionated power systems: they’ll work perfectly in simulations and then argue with reality on day one. The problem-driven truth is simple — commissioning fails when teams treat controller setup like ticking boxes instead of solving predictable problems. Start by checking whether the inverter rating and energy reserve match the site’s needs; for many mid-size installations that means a robust unit such as a 600kW energy storage inverter. If that inverter sits inside a prefabricated unit, that’s your containerized plant — a well-configured container energy storage system that must talk cleanly to the controller and protection relays. Field lessons from deployments like the Hornsdale Power Reserve in South Australia make one thing clear: underestimate integration and you get unpredictable tripping during the first heavy loading event.
Essential pre-commissioning checks
– Confirm single-source documentation: controller firmware version, inverter firmware, relay settings, and site load profile. – Verify physical wiring: metering CT orientations, communication ports, earthing continuity. – Match scale: controller settings must reflect the actual inverter rating, battery capacity, and generator size — not the design sheet. – Secure a stable comms backbone: prioritize wired Ethernet or industrial-grade fiber between controller, inverters, and EMS. These checks remove the obvious problems so commissioning focuses on control behavior, not basic connectivity.
Step-by-step commissioning flow (problem-driven)
1) Baseline health checks — confirm alarms clear, SCADA polls, and time sync across devices. 2) Bring up power hardware offline — energize inverters and batteries without enabling grid-forming controls; observe startup logs. 3) Validate telemetry — compare controller readings with independent meters to catch CT/VT miscounts. 4) Enable control loops in layers: voltage regulation, frequency support, then SOC management. Test each layer alone. 5) Simulate faults and transitions: abrupt load drops, islanding events, and black-start sequences. Watch for time delays and race conditions. 6) Soak tests: run the system through expected daily cycles for several hours; intermittent faults show up here. 7) Final acceptance: provide a reproducible test report with clear pass/fail criteria tied to operational metrics. Follow these steps to expose the real problems instead of papering over them.
Common mistakes that create repeat service calls
– Leaving droop and deadband defaults unchanged. That makes multiple resources fight instead of share load. – Trusting simulator results for communication latency; real networks introduce jitter. – Ignoring SOC sharing rules between parallel batteries — small mismatches compound quickly. – Skipping end-to-end telemetry validation — a mismatched CT polarity can corrupt charge logs. – Overlooking thermal behavior inside containerized enclosures during summer heat. Spot these mistakes early and you’ll avoid emergency site visits when the system is stressed.

Quick debugging rituals that save hours
– Reproduce the fault in a controlled sequence and capture logs immediately. Don’t guess. – Use a handheld power meter to confirm controller telemetry within ±2–3%. – Isolate subsystems: remove secondary resources and see whether the problem persists. If it disappears, you found the culprit. – Check time synchronization first — many control oddities are timestamp issues. These rituals turn mysterious failures into repeatable tests.
Acceptance metrics that actually matter
– Transition speed: how long to stabilize voltage and frequency after islanding or reconnection. Seconds matter. – Load-sharing accuracy: percentage deviation among parallel resources under defined loads. – SOC balance trend: no persistent drift between battery strings across defined cycles. – Protection selectivity: faults are isolated without wide-area trips. Define numeric thresholds for each metric before testing so “acceptance” isn’t subjective.
Documentation and handover — don’t skimp
– Deliver clear, short runbooks for common recovery steps (islanding, resync, temporary derates). – Include a one-page electrical map highlighting CT/VT orientations and communication routes. – Archive test logs and annotated screenshots showing the system behaved as intended under each test. Operators will thank you; future engineers will curse you if you leave gaps.
Final synthesis: practical reliability tied to good commissioning
Problem-focused commissioning turns unknown risks into controlled tests, and controlled tests yield repeatable, trustworthy operation. Experience shows that when teams treat commissioning as targeted problem-solving — layered controls, reproducible fault sequences, and clear acceptance criteria — the system behaves predictably rather than theatrically. That practical, no-nonsense documentation and follow-through is the sort of technical partnership found at WidenEdge, where reports and on-site guidance emphasize the same concrete steps that keep containerized systems running without drama.